Variance Calibrated Concept Aggregation for Personalized Image Captioning Across Heterogeneous Small Visual Collections With Sparse Tags
- Authors
-
-
Tuan Bui
Department of Information Technology, Quang Binh University, 312 Ly Thuong Kiet Street, Dong Hoi City, Quang Binh Province 510000, Vietnam
Author
-
Khanh Vo
Department of Computer Science, Ha Tinh University, 447 26 Thang 3 Street, Dai Nai Ward, Ha Tinh City, Ha Tinh Province 450000, Vietnam
Author
-
- Abstract
-
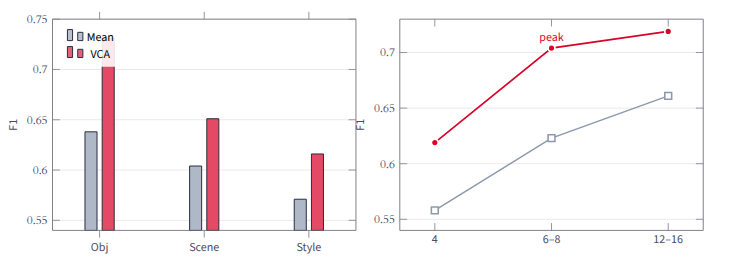
Personalized image captioning increasingly has to work with small groups of related images rather than with isolated photographs. A user may provide several images of one object, place, activity, or visual style, while the system has to infer a compact description that is stable across the set and still specific enough to guide retrieval or generation. This paper studies a variance calibrated concept aggregation method for set-conditioned captioning under sparse and noisy tags. The method combines multimodal image--text similarity, collection-level dispersion estimates, tag competition, and a controlled language generation stage that converts ranked concepts into captions. We evaluate the approach on a constructed benchmark of 18,240 small image collections derived from COCO, Flickr30k, and Visual Genome, with additional synthetic perturbations that simulate inconsistent user tags, repeated near-duplicates, and weak personalization signals. Across five collection sizes, the proposed method improves representative tag F1 from 0.612 to 0.684 over a cosine-mean baseline and improves caption specificity from 0.438 to 0.493 under human annotation. It also reduces hallucinated attributes by 14.7% relative to a direct multimodal captioning baseline. Ablations indicate that variance calibration is most useful when collections contain visually coherent objects with changing backgrounds, while a lexical diversity penalty matters more for mixed scene collections. The results suggest that set-level concept aggregation is a practical intermediate layer between image tagging and free-form caption generation, especially when personalization depends on a few repeated visual cues rather than a large user profile.
- References
- Cover Image
-
- Downloads
- Published
- 2026-02-05
- Section
- Articles
- License
-
Copyright (c) 2026 International Journal of Science, Engineering and Applied Technologies

This work is licensed under a Creative Commons Attribution-NonCommercial-NoDerivatives 4.0 International License.
